

Cisco Meraki Large Scale Design Best Practice
Overview
Cisco Meraki is a cloud-managed networking platform that centralizes configuration, monitoring, firmware delivery, and operational telemetry in the Meraki Dashboard. The platform supports security appliances, switches, access points, cameras, sensors, cellular gateways, and related services.
This guide covers design-level decisions for multi-site Meraki deployments. It includes organization and network structure, licensing, administrator access, configuration templates and cloning, switching interoperability, wireless roaming domains, SD-WAN, firmware rollout, monitoring, API automation, and operational controls.
This guide does not replace product deployment guides, product-specific sizing, a wireless site survey, a security review, or a current licensing and support entitlement review. Validate every design against the hardware models, software versions, regulatory domain, and operational requirements of the proposed deployment.
General design principles
- Make the organization boundary deliberate. An organization is a management and licensing container; it also defines the scope of the Meraki SD-WAN domain.
- Make the network boundary reflect a real operational boundary such as a site, LAN, roaming domain, or product-specific configuration set.
- Standardize repeatable configuration with templates or golden networks, then use tags and API automation to express controlled variation.
- Treat template changes, firmware changes, administrator changes, and automation changes as production changes with an owner, a test path, and a rollback or recovery plan.
- Keep source records for configuration intent, addressing, ownership, exceptions, and validation results outside the dashboard so the deployment remains operable during an access or cloud-management outage.
Target audience
- Enterprise network architects planning multi-site Meraki deployments
- IT operations teams managing thousands of Meraki devices
- Managed service providers designing multi-tenant Meraki environments
- Network engineers integrating Meraki into existing Cisco Catalyst or third-party switch fabrics
Platform Architecture
The Meraki Dashboard is the management plane. Devices establish an encrypted, out-of-band connection to the Meraki cloud for configuration synchronization, firmware delivery, and telemetry. Customer data traffic is forwarded through the customer network and does not traverse Meraki data centers as a transit path. Additional details about the platform architecture can be found here.

Privacy, Security, and Regulatory Compliance
Cisco Meraki's cloud-managed architecture is designed to meet the security and compliance requirements of large-scale enterprise deployments. All management-plane traffic between Meraki devices and the Meraki Dashboard is encrypted using TLS 1.2/1.3, and data-plane traffic traverses customer-owned infrastructure directly without backhauling through Meraki cloud infrastructure except where configured to do so in Radius Proxy
Meraki's cloud infrastructure maintains SOC 2 Type II and ISO/IEC 27001 certifications, and Cisco Meraki holds FedRAMP Class C (Moderate) Certification, enabling deployment in U.S. federal and regulated public-sector environments.
For organizations subject to data residency requirements, Meraki offers dedicated regional cloud infrastructure aligned with GDPR obligations for EU-based customers, and supports compliance with HIPAA, PCI-DSS, and CIPA through documented shared-responsibility controls and network segmentation capabilities native to the platform.
You can access the Cisco Meraki Trust Center website for more information.
Cloud connectivity and firewall policy
A device must reach the Meraki cloud through the firewalls and routers between the device and the internet. The authoritative destination list, ports, and purposes are available in the Dashboard under Help > Firewall info. Use that page as the source for allow-list changes because destinations and service requirements can change.
- Permit the outbound connections listed by Help > Firewall info for the applicable Meraki service and region.
- Confirm that stateful inspection, TLS inspection, proxy behavior, DNS resolution, and certificate handling do not interrupt the device management tunnel.
- For stateless firewalls or asymmetric paths, configure the corresponding return traffic explicitly.
- Test cloud reachability from each site archetype before shipping a zero-touch deployment. A device that cannot reach the cloud cannot retrieve its intended configuration or report health and will be marked offline.
Configuration resilience
Meraki devices store their active configuration locally and continue forwarding traffic when cloud connectivity is temporarily unavailable. The loss of dashboard connectivity still prevents configuration changes, firmware operations, and current telemetry from being exchanged. Design local forwarding and failure handling so the site remains safe and useful during an extended management-plane outage.
The dashboard protects against some invalid changes by marking a new configuration safe only after the device has remained connected for the documented validation interval. Do not treat this behavior as a substitute for testing. Stage high-blast-radius changes in an unbound network, a pilot group, or a maintenance window with an explicit recovery path.
| Event | Timer |
| Configuration marked as safe | 30 minutes |
| Configuration rollback to previous configuration |
2 hours without a successful configuration fetch and 4 failed configuration fetch attempts For MG cellular devices only: 2 minutes |
Catalyst devices running native IOS-XE mark configuration as safe by copying running-config to startup-config. A reboot before the 30 minute timer will boot the device into startup-config, then dashboard reapplies the new configuration. The 30 minute timer reset when the configuration is reapplied by the dashboard.
Organization and Network Structure
The hierarchy is Account > Organization > Network > Device. An account identifies an administrator. An organization is a logical container for networks, devices, licensing, administrators, templates, and organization-level settings. A network contains the devices and configuration that should operate together.

Device limits
Maximum Recommended Scaling Guidelines
| Item | Limit |
| Total Devices Deployment Size | Unlimited |
| Devices per Organization | 50,000 (MX / Secure Routers recommended max is 15k / 30k in non-HA / HA deployments |
| Devices per Network (standalone and combined) | 5,000 |
Devices per Network limits
| Product Type | Limit |
| Access Points | 5000 |
| Switches | 5000 |
| MT | 1700 |
| MV | 1000 |
| MX | 2 |
| MG | 4 |
| CG | 2 |
| WLC | 2 |
Choosing a single or multiple organizations
Use one organization when the deployment can share the same licensing model, administrator governance, firmware coordination, templates, and Auto VPN domain. A single organization reduces duplicated configuration and makes cross-site reporting and automation easier.
Organizations can be split with the help of support, but cannot be combined. Organizations can be combined using the network move tool to move networks to one organization.
Use multiple organizations when a boundary changes the operational, legal, or security model. Common drivers include regional data sovereignty, separate business units, distinct service-provider tenants, separate SD-WAN domains, and a deployment that would otherwise exceed the organization scale guidance.
|
Driver |
Why the boundary matters |
Control required |
|
Regional or regulated operation |
Organizations are hosted in a service region and may use a dedicated regional service. |
Confirm residency, administrator access, API endpoint, and product availability with Cisco. |
|
Separate SD-WAN domains |
Each organization is a distinct SD-WAN domain. |
Document the inter-domain routing or security design separately. |
|
Business-unit isolation |
Organization-level policies, licensing, inventory, and administrators are separated. |
Define shared services and the owners of each organization. |
|
Service provider tenancy |
Customer ownership, access, billing, and service tiers may require isolation. |
Choose one organization per customer or service only after confirming the support and billing model. |
|
Scale headroom |
A large deployment may approach the organization or network device guidance. |
Split before the limit and automate parity where appropriate. |
For most enterprises, create one network per physical site or LAN. A network shares configuration such as SSIDs and routing information, and an MX network supports one appliance or two appliances when one is the warm spare. Do not merge sites merely to reduce network count if the sites need different routing, roaming, firmware, administrator, or change boundaries.
Data sovereignty and latency across multiple geographic regions
If your business exists in more than one of the regions of The Americas, Europe, Asia/Pacific, China, then consider having separate organizations for each region. Each dashboard organization is hosted in a specific region, and your country may have laws about regional data hosting, such as GDPR compliance and other data sovereignty laws. Latency on management traffic could also be a deciding factor on where to host your organizations.
In addition to regionally organizations within Cisco Meraki’s global service, dedicated services exist for US Government (FedRAMP Class C (Moderate) Certification), Canada, China, and India geographies. These services are isolated from the global service within its own servers and datastores for enhanced privacy and security. Separate login accounts must be created for each individual service, with no connection between any service.
Meraki’s services can be accessed via the following sites:
| Region | Site |
|
Global |
|
|
US Government (FedRAMP) |
|
|
Canada |
|
|
China |
|
|
India |
Multi-organization governance
- Assign an owner, service region, business purpose, SD-WAN relationship, and support escalation path to every organization.
- Keep organization names, network names, tags, templates, and administrator groups consistent enough for search and automation, while retaining the region or business boundary in the name.
- Maintain parallel templates and firmware standards deliberately. Templates and firmware coordination are organization-scoped and do not automatically create parity across organizations.
- Claim hardware by order number into the intended organization when possible. Confirm regulatory domain and shipping-country requirements for wireless hardware before ordering.
- Use Global Overview or an approved reporting and automation layer for fleet visibility; do not assume that a user who can see several organizations has a single shared configuration scope.
Licensing and enforcement
Maintaining active licenses is critical to warranty and service continuity. Licenses for hardware include built-in lifetime warranty (with some exceptions) and are required for connectivity to the Cisco Meraki dashboard.
There are currently three licensing models customers can choose depending on their billing needs.
License entitlement and renewal dates are readily accessible on the Meraki dashboard in the Organization menu. Access to the license pages require organization level privileges.
Summary of licensing models
|
Co-termination |
Subscription |
EAs/WPAs |
|
|
Single license and expiration date per organization |
✅ |
✅ |
✅ |
|
Single license and expiration date across multiple organization |
❌ |
❌ |
✅ |
|
Per network licensing/renewals |
❌ |
✅ |
❌ |
|
Allows for overconsumption |
❌ |
❌ |
✅ |
|
Mid-term changes |
❌ |
✅ |
✅ |
|
Flexible billing options (subject to credit approvals) |
❌ |
✅ |
✅ |
Licensing fit
|
Model |
Best fit |
Important behavior |
|
Co-termination |
A single organization-wide renewal date and pooled license consumption. |
Licenses are averaged into one organization expiration date. A lapse can affect the organization as a whole. |
|
Subscription |
Network, group, or organization-level subscriptions with mid-term changes. |
Licensing can be scoped more narrowly; unlicensed devices may continue forwarding while dashboard configuration is disabled for them. |
|
Enterprise Agreement |
A consolidated Cisco agreement spanning eligible organizations and suites. |
Consumption and billing are reconciled through the agreement terms and True Forward process. |
|
Whole Portfolio Agreement |
A portfolio-wide agreement across Cisco products. |
The dashboard experience resembles an unlimited subscription; billing is handled through the agreement. |
Administration and roles
Dashboard access is a production control. Use named administrators for human actions, SAML/SSO for enterprise identity where supported, and dedicated local service accounts only where an API key or recovery path requires them. Apply least privilege at the narrowest useful scope.
First access and account recovery
The first organization administrator is created with a local dashboard account. Establish a second controlled recovery account before onboarding the wider team, document the owner and storage location for recovery material, and enforce two-factor authentication for local administrators.
Administrator roles
|
Role |
Scope |
Use |
|
Organization full |
Organization or selected networks |
Unrestricted platform owners who manage licensing, inventory, administrators, templates, and organization settings. |
|
Observer (read-only) |
Organization or selected networks |
Auditors, managers, or support personnel who need visibility without change authority. |
|
Network full |
Selected networks |
Site or service owners responsible for configuration within an approved boundary. |
|
Network read-only or monitor-only |
Selected networks |
Operations and service teams that need diagnosis or reporting without configuration authority. |
|
Switch port manager |
Network and switch-port tags |
Teams that manage defined switch ports without broad organization access. |
|
SSID manager |
Selected network |
Wireless operations teams that manage SSIDs without broader network configuration. |
|
Client monitor |
Selected network |
Troubleshooting staff who need monitoring data but no write access. |
|
Guest ambassador |
Selected network |
Staff who manage guest authentication users and portal access. |
|
Camera footage and sensor |
Selected network |
Operators with full or read-only access to sensor data and configured camera-footage privileges. |
Full access to organization and networks offers similar functionality but differ with network administrators only being able to access networks they are assigned to. Additionally, network administrators will not be able to access any functionality within the “Organization” menu. Organization administrator-only pages include, but not limited to, licensing, inventory, change logs, and early access (beta) pages.
Custom roles (currently in BETA testing)
In many companies, different parts of the network may be managed by different teams, and it may be undesirable to have an administrator have full access to a network. With custom roles, we can now fine-tune administrator permission to specific product families. Currently, restricting administrator to Security & SD-WAN, Switching, and Wireless networks within a combined network is available. This functionality can be enabled in the Early Access menu today.
Improvements to role-based access control is ongoing. Reach out to your Cisco account management team for more information.
SAML and API access
Separate human identity from application identity. SAML/SSO controls how administrators sign in to the Meraki Dashboard; API authorization controls how an integration calls the Dashboard API. Where the organization and application support OAuth 2.0, an appropriately authorized SAML/SSO administrator can approve the application grant without exposing a personal API key. Use the least-privileged model that matches the automation.
- OAuth 2.0 app-scoped access — Use this for third-party applications and organization-wide automation. Register the application, request only the required OAuth scopes, and have an appropriately authorized organization administrator approve the grant. OAuth access tokens are time-limited and refreshed through the OAuth flow; protect refresh tokens as credentials. A personal Dashboard API key is not required.
- API-key admin-scoped access — Use this for personal scripts or tasks that must execute with a specific administrator’s role. An API key inherits the permissions of the administrator who owns it. SAML/SSO administrators cannot generate personal API keys, so create a dedicated local administrator only when API-key authentication is required; assign the minimum organization or network scope, store the key in a secrets manager, and rotate or revoke it on a defined schedule.
Refer to the Configuring SAML Single Sign-on for Dashboard and OAuth 2.0 Integration articles for detailed instructions on how to set up SAML/SSO and OAuth 2.0 login.
Individual SAML/SSO dashboard administrators cannot view or generate API keys, which is an important consideration for automation strategies.
Network design standards
Large deployments need a standard configuration model that allows common behavior to be changed centrally without hiding the site-specific settings that require local judgment. Use templates for dynamic standardization, golden networks for static cloning, and tags for controlled selection and access.
Templates versus cloning
|
Method |
Behavior |
Use when |
|
Configuration template |
Bound networks inherit the template configuration and receive later template changes. |
Many sites share a stable design and should remain aligned over time. |
|
Golden network clone |
A new network receives a point-in-time copy; later changes do not propagate automatically. |
The site needs a starting baseline with substantial local variation or an API-driven workflow. |
|
API-driven configuration |
Scripts read, validate, and write selected resources using explicit logic. |
The deployment needs conditional behavior, cross-organization coordination, drift detection, or integration with CI/CD and ITSM. |
Template design
For every template, document a configuration design that states what the template owns, what the site may override, and what must be validated after a change. At minimum, include site archetype, SSIDs, VLAN names and purpose, subnetting mode, baseline security policy, standard port profiles, firmware intent, tags, and the list of approved local overrides.
- Use one template per site archetype rather than one universal template with many conditional exceptions.
- Use unique subnetting for VLANs that participate in site-to-site VPN. Use the same subnetting only where identical addressing is intentional and VPN overlap is not required.
- Test template changes in a staging network and a pilot group before broad rollout. A template change can affect every bound network.
- Review local overrides periodically. Overrides are useful for exceptions, but uncontrolled overrides turn the effective configuration into an undocumented fork.
Tags and naming
Tags can identify networks, devices, switch ports, and Systems Manager devices. Use a short documented taxonomy for geography, site archetype, lifecycle, service tier, compliance scope, and operational ownership. Apply tags during provisioning and use them as inputs to access scope, firmware groups, API filters, and reporting.
|
Tag family |
Example pattern |
Control or query |
|
Geography |
geo-us-east |
Regional reporting and administrator scope. |
|
Site archetype |
type-retail |
Template, firmware, and deployment workflow selection. |
|
Lifecycle |
life-pilot / life-prod |
Staged rollout and change targeting. |
|
Service tier |
tier-critical |
Alert routing and maintenance policy. |
|
Ownership |
owner-field-ops |
Escalation and visibility. |
|
Compliance |
scope-pci |
Audit queries and restricted administration. |
Network cloning
Create device-free golden networks for repeatable site provisioning when the desired result is a static starting point. Keep the golden network under change control, verify the clone output, and apply site-specific values through a documented checklist or API. A clone is not a synchronization relationship; changes to the golden network do not update networks that were cloned earlier.
Switching design considerations
IOS-XE Catalyst switches on the Meraki Dashboard
IOS-XE Catalyst switches can be managed on the Meraki Dashboard using two different modes.
| Configuration Source Mode | Configuration Support | API Support (coming soon) |
| Cloud |
Dashboard UI configuration CloudCLI terminal (read only) CLI Profiles for custom configuration (coming soon) *Local and remote SSH/Telnet login is disabled. |
show commands only |
| Device |
Local configuration (SSH/Telnet/NETCONF) CloudCLI terminal (read and write) |
show and configuration commands |
Spanning-tree interoperability
Meraki MS switches use a single RSTP spanning-tree instance and interoperate with common Cisco spanning-tree protocols, but the interoperability behavior determines where the root bridge can be placed and which VLANs must remain on trunks.
|
Adjacent Protocol |
Meraki Behavior |
Design Requirements |
|
RSTP |
Native and compatible with the MS switching model. |
Use deliberate root priority and verify the resulting topology. |
|
MSTP |
MS switches do not support multiple MST instances and interpret the MST region as a single RSTP view. MS390/C9300-M uses a single MST instance by default. |
Use a consistent single-instance design and verify boundary behavior. |
|
PVST+ or Rapid PVST+ |
The MS side participates through the VLAN 1 spanning-tree instance; the MS side may operate in legacy STP/RSTP behavior. |
Allow VLAN 1 on trunks, configure both sides as 802.1Q trunks, and keep the MS switch out of the root-bridge role. |
Mixed Catalyst and Meraki L2 STP considerations
- Prefer converting a Catalyst environment to a single-instance MSTP design before inserting MS switches into a PVST+ or Rapid PVST+ path.
- If PVST+ or Rapid PVST+ remains, run a spanning-tree instance on VLAN 1 across the relevant switches and allow VLAN 1 on every interconnecting trunk so BPDUs can be seen by the MS switch.
- Configure the Catalyst and MS ports as matching 802.1Q trunks. A port-type mismatch can cause PVST simulation or port-inconsistency blocking.
- Keep the Catalyst distribution or core layer as the STP root. Do not make an MS switch the root bridge in a mixed PVST+ environment.
- After changes, verify the root bridge, blocked ports, VLAN 1 allowance, trunk mode, native VLAN, and the expected forwarding path for every redundant link.
Layer 2 boundaries and link aggregations
Keep Layer 2 domains bounded by a deliberate access, distribution, or building boundary. Use link aggregation where the switch models and upstream design support it, and verify that the member links terminate in a compatible logical system. The goal is a predictable failure domain; more physical links do not automatically improve convergence or eliminate the need for spanning tree.
Wireless design considerations
Wireless network boundaries must reflect RF adjacency and client-mobility requirements. A Meraki network is the fast-roaming domain in which access points share client PMK information. Splitting adjacent APs across networks can turn a fast roam into a full reauthentication.
MCG Campus Gateway
Use an MCG Campus Gateway when a large campus needs centralized wireless traffic termination from cloud-managed access points. The MCG tunnels SSID traffic from APs to a central gateway, allowing client VLANs to remain in the core instead of being extended across the access layer, while supporting client roaming across Layer 3 boundaries without interrupting sessions. It also provides a scalable, highly available design with fewer wired-side changes because the APs and gateway only need IP reachability across the existing network underlay. For smaller or simpler sites, locally switched MR deployments may be easier to operate; MCG is most valuable when centralized policy, large-scale roaming, segmentation, and campus-wide wireless scalability justify the additional gateway layer.
Wireless Controller monitoring
Wireless Controllers are represented in the Meraki Dashboard primarily for monitoring and operational visibility. Dashboard can provide controller health, interface status, high-availability state, associated access points, client information, and relevant events; however, the Wireless Controller remains a monitor-only device rather than a Dashboard-configured product. Do not include Wireless Controllers in cloud configuration templates or standard Dashboard firmware-upgrade workflows. Manage configuration and software lifecycle activities through the controller’s supported local or external management process.
Roaming-domain sizing
Start with a building or another physical area with a clear RF boundary as the smallest roaming domain. Place RF-neighbor APs in the same Meraki network and the same management VLAN where the design requires fast roaming. APs must be able to exchange client PMK information between APs using source port 23541 to destination port 35213.
|
Roaming condition |
Client addressing |
Design implication |
|
Same SSID and same VLAN |
Client keeps the IP address. |
Preferred for seamless Layer 2 roaming when the switching design can support the shared VLAN. |
|
Same SSID and different VLAN |
Client session may break and require address validation or DHCP behavior. |
Use only when the application and client population tolerate the interruption. |
|
Layer 3 roaming or tunneling |
A mechanism can preserve the client IP across VLAN boundaries. |
Validate scale, latency, support, and fast-roaming behavior for the specific design before adoption. |
The same-VLAN choice can expand the broadcast domain across access switches or buildings. Balance roaming continuity against MAC and ARP scale, DHCP scope size, broadcast and multicast exposure, failure containment, and security segmentation. A roaming domain should be designed from both the RF map and the wired topology.
SSID and VLAN design
- Keep the SSID set small. Every enabled SSID adds management-frame overhead and reduces airtime available for client traffic.
- Use a consistent SSID purpose, authentication method, VLAN or named-VLAN policy, firewall policy, and ownership across the roaming domain.
- Use AP tags when a subset of APs needs a specific VLAN or RF behavior. Record the tag-to-policy relationship as part of the template contract.
- Keep client VLANs, AP management VLANs, and infrastructure management controls distinct unless the design explicitly requires otherwise.
RF profiles and AI-RRM
Use RF profiles to express the intended channel width, transmit-power range, minimum bitrate, and receiver sensitivity for an area. AI-RRM can adjust channel and power settings based on the observed environment, but it operates at the Meraki network scope. APs that are RF neighbors should therefore be in the same network unless a tested boundary is intentional.
- Use 20 MHz channels as the default starting point for most enterprise 5 GHz deployments; use wider channels only where the client density, channel availability, and capacity model justify them.
- Use a site survey or measured telemetry to set minimum bitrates and power boundaries. Raising the minimum bitrate or receiver sensitivity can improve reuse and roaming, but can also create coverage holes.
- Enable AI-RRM within documented guardrails and validate a pilot area after RF-profile changes. Avoid simultaneous, unconstrained changes across a large campus.
- Disable wireless meshing when it is not required so APs do not advertise mesh service that consumes airtime.
- For 6 GHz, validate regulatory domain, client capability, security requirements, and channel-width policy before enabling the band. WPA3 requirements apply to 6 GHz operation.
MX and SD-WAN design considerations
Meraki Auto VPN builds the overlay between MX appliances in the same organization. Because the organization defines the Auto VPN domain, moving sites into separate organizations also creates separate SD-WAN domains unless an external interconnection design is added. Refer to the full Auto VPN Hub Deployment Recommendations for additional considerations.
Hub-and-spoke design
Use a small set of stable hub locations for shared services, data centers, or corporate resources. Spokes build tunnels to their configured hubs and do not automatically form spoke-to-spoke tunnels. A hub-and-spoke design reduces the number of relationships that each branch must maintain and makes the intended traffic path easier to operate.
|
Design choice |
Recommendation |
Reason |
|
Datacenter role |
Use a one-armed VPN concentrator or routed MX design that matches the data-center routing architecture. |
Separates overlay termination from the user LAN when appropriate. |
|
Hub redundancy |
Use a warm spare or equivalent high-availability design at critical hubs and provide datacenter redundancy. |
Maintains service when a hub appliance or facility fails. |
|
Branch uplinks |
Use dual WAN uplinks where the service and circuit design justify them. |
Auto VPN can build tunnels on reachable uplinks and provide dynamic failover. |
|
Routing upstream |
Use OSPF or BGP where the upstream network and scale require dynamic route exchange. |
Avoids large, manually maintained route tables at the data center boundary. |
|
Traffic model |
Prefer split tunnel for branch access to private networks unless a full-tunnel security or inspection requirement is explicit. |
Avoids unnecessary backhaul and preserves local internet breakout. |
In very large AutoVPN deployments, additional custom functionality like disabling hub to hub routing and summarizing spoke routes can be enabled. Reach out to your account systems engineer or support to discuss these changes.
Overlay scale and route behavior
- Count hubs, spokes, uplinks, advertised subnets, and expected traffic paths before deployment. Dual WAN and multiple hubs increase tunnel and route relationships.
- Keep Auto VPN hub roles intentional. Configuring many devices as hubs can create more hub-to-hub and route relationships than a large deployment needs.
- Use the current Auto VPN static-routing scaling features only with Cisco Support and Solutions Engineering involvement when the design requires suppressing hub-to-hub tunnels, spoke-to-spoke routes, or route tracking behavior.
- Do not place the hub role in a template unless the current product guidance explicitly supports that model for the selected network type. Verify the resulting VPN topology after binding or cloning.
Firmware management
Firmware is delivered through the Meraki Dashboard. Use the documented release channels and a staged schedule that separates lab, pilot, and production populations. The configured network firmware and the version installed on a device can differ temporarily during an upgrade or when a device model does not support the configured release.
There are three distinctive firmware release types:
|
Firmware Type |
Recommended Usage |
|
Recommended Release |
Enterprise and mission-critical production after validation. |
|
Generally Available |
Production networks where the release has passed the organization validation process. |
|
Beta |
Labs, pilots, and targeted testing; do not use as the default production standard without explicit approval. |
Network firmware vs. device firmware
There is often confusion between the configured network firmware and the firmware installed on a device. While devices are designed to inherit the firmware configured on the network, this may not always be the case. There are two reasons why this could be the case.
Device is configured to upgrade
When a device is added to a network or a network has been scheduled to upgrade to a new version, the device will show its existing version while the upgrade takes place. Once upgraded, the device will display to correct installed firmware version.
Not running configured version/Firmware not supported on device
When a device is running a firmware that does not match the configured network version, you will see the "Not running configured version" noted in the firmware version section. This may occur if firmware upgrades have been paused, the firmware upgrade has failed, or the version is not supported on the device.
Because no restrictions exist for adding older end-of-support devices to networks, scenarios may arise where a legacy device lacks compatibility with the latest firmware version. In such cases, the device will be provisioned with the most recent firmware release that it supports. Network capabilities may also be restricted from configuration if any device within the network lacks support for a particular feature, as the management dashboard employs lowest common denominator logic when determining which network features can be enabled. Refer to the Product Firmware Version Restrictions document for minimum and latest supported firmware versions.
Reach out to Cisco Meraki Technical Support to verify firmware availability in these cases.
Identifying configured firmware version
Existing firmware version for a network can be found at Organization > Monitor > Firmware Upgrades. The version on a specific device can be found on the network device status page.

Upgrade sequence and availability
Mechanisms have been put in place to reduce downtime for highly available networks. Devices continue to operate during download and install; downtime only occurs during reboot/reload. Expected real downtime for all devices is 5 minutes during the reboot after firmware installation is complete.
| Product Family | Upgrade Sequencing | Firmware Pre-Download Support | Local Firmware Fetch Support |
| MX SD-WAN and Security Appliance | Devices in a VRRP pair upgrade sequentially, with a 15-minute delay between the primary and secondary. Expected downtime for a single device is approximately 5 minutes. | No | No |
| MS Switches |
Switches each upgrade individually. If a downstream Meraki switch is detected, a 25 minute wait timer is initiated after installation to ensure all downstream switches complete their installation before reboot. Staged upgrades allow manual grouping and sequencing of switches for finer control. |
No | No |
| IOS-XE Switches | Staged upgrades allow manual grouping and sequencing of switches for finer control. | Automatic | No |
| MR Wireless |
Minimize upgrade time upgrades as many APs as possible simultaneously. OR Minimize client downtime avoids upgrading adjacent APs simultaneously. |
Optional via Firmware Upgrade Scheduler (requires minimum MR 32.1.x firmware) |
Yes (requires minimum MR 32.1.7 firmware) |
| MCG Campus Gateway | Immediate upgrade during schedule time and reboot after installation | Automatic | No |
| All other product families (MG, MV, MT) | Immediate upgrade during schedule time and reboot after installation | No | No |
Firmware Pre-Download Behavior: Begins 24 hours before the scheduled upgrade when the upgrade is scheduled at least 24 hours in advance. If scheduled less than 24 hours ahead, the download begins immediately.
Local Firmware Fetch: Allows an AP to download firmware from Dashboard and distribute the image to other APs over the LAN.
For networks utilizing both SD-WAN and Security Appliances and Switch devices, always upgrade the MX appliance first and wait until it is online on the new firmware before upgrading downstream switches. If a downstream switch reboots on new firmware and cannot connect to the Meraki Cloud (because the upstream MX is mid-reboot), it may assume the new firmware cannot connect and revert to the previous version as a fail-safe.
Firmware image size
| Product Family | Approximate Image Size |
| MX SD-WAN and Security Appliance | 60 MB |
| MS Switches | 30 MB |
| IOS-XE Switches | Up to 700MB |
| MR Wireless | 15 MB |
| MCG Campus Gateway | Up to 2GB |
| MG Cellular Gateways | 40 MB |
| MV Cameras | 110 MB |
Image size is approximate and will differ across different firmware versions.
Automation and programmability
The Dashboard API is a RESTful interface organized around organizations, networks, devices, configuration resources, monitoring resources, and live tools. Use it to remove repetitive work while keeping changes reviewable and bounded. A script that can reach every organization is a production control plane and must be governed accordingly.
API architecture
The Meraki API follows a resource-based hierarchy: Organizations contain Networks, which contain Devices. Services are grouped by function: CONFIGURE (manage cloud configurations), MONITOR (return status and history), and LIVE TOOL (directly interact with devices). The base URI for each region is:
|
Global |
|
|
US Government (FedRAMP) |
|
|
Canada |
|
|
China |
|
|
India |
API key management
API keys are associated with the dashboard administrator account that generates them and inherit the same permissions. Understanding key lifecycle management is critical for enterprise security:
-
Create a dedicated local administrator for automation; do not use a personal administrator account for unattended jobs.
-
Grant only the organization or network scope required by the job. Remember that an API key inherits the creator account permissions.
-
Store keys in a secrets manager, rotate them on a defined schedule, and revoke keys when the owner, integration, or authorization boundary changes.
-
Separate read-only inventory and monitoring jobs from write-capable deployment jobs when the operating model allows it.
Rate limiting
The Meraki API enforces rate limits to protect the platform at 10 API calls per second per organizations, with the ability to burst to 30 API calls per second. When rate limits are exceeded, the API returns HTTP 429 responses with a Retry-After header. The official Meraki Python SDK includes automatic retry logic with exponential backoff for 429 errors. For custom integrations, implement retry logic with appropriate delays and request batching with Action Batches.
API Analytics, accessible under Organization > Configure > API & Webhooks, provides visibility into API consumption across your organization. Use this data to identify integrations approaching rate limits and optimize request patterns.
Push API
Use Push API when you need event-driven updates for supported topics and repeated Dashboard API polling would consume API capacity or delay operational response. An organization subscribes to a topic, and Meraki sends updates to an HTTPS webhook endpoint. Push API notifications do not count against the organization’s API rate limit.
Common automation use cases
-
Provisioning: Create organizations, networks, and claim devices in bulk. Pre-stage configurations and bind to templates automatically.
-
Cross-organization management: Push firmware schedules, administrator changes, and firewall rules across multiple organizations.
-
Network migration: Move devices and configurations between organizations. Since devices lose their configuration when removed from a network, API scripting is the only reliable way to preserve settings during migration.
-
Compliance auditing: Query device tags, firmware versions, and configuration state across the fleet. Identify drift from golden configurations.
-
Custom reporting: Extract performance metrics, client statistics, and event data for dashboards beyond what the native dashboard provides.
-
Event-driven automation: Combine webhooks with API calls to automatically isolate compromised devices, adjust bandwidth shaping, or generate ITSM tickets.
Infrastructure as Code (IaC)
For organizations already using IaC practices, the Meraki API integrates with Terraform and Ansible to bring network configuration under the same version control and CI/CD workflows used for application infrastructure. Treat template changes like code: version them, test in staging, and roll out through a deployment pipeline.
The official Meraki Python SDK (available via pip install meraki) provides built-in pagination control, automatic retry on rate limits, call simulation for previewing changes, and structured logging. It is the recommended starting point for Python-based automation.
Cisco Workflows
Cisco Workflows is a cloud-hosted automation engine available natively within the Meraki dashboard, accessible at no additional cost under the Automation menum, or in Cisco Cloud Control. It provides a low-code/no-code environment for building, executing, and managing automations across Cisco and third-party systems. For large-scale enterprise deployments, Workflows fills the gap between simple API scripting and full-scale orchestration platforms, enabling network teams to automate Day 0 through Day 2 operations using a simple, visual, drag-and-drop editor without writing or maintaining custom code. Workflows also provides a catalog of pre-built automations in the Workflows Exchange that can be used as is or easily customized to your use case. Refer to the Cisco Workflows documentation for detailed steps on getting started.
Common workflow patterns in large-scale Meraki deployments include:
-
Cross-organization firmware scheduling: A workflow that iterates across all organizations an API key has access to, schedules firmware upgrades by network tag, and pauses for administrator approval before executing.
-
Switch port configuration cloning: Copying port configurations from a source switch to a target switch across sites, handling edge cases like trunk ports with “allow all” VLAN configurations.
-
Multi-domain provisioning: Combining Meraki network creation with ISE policy deployment and Catalyst Center onboarding in a single automated workflow, reducing new-site provisioning from hours to minutes.
-
Compliance and drift detection: Scheduled workflows that query device configurations, compare against golden standards, and generate reports or ITSM tickets for deviations.
Workflows design best practices
When building custom workflows for enterprise environments, the following practices from Cisco’s published guidelines should be followed:
-
Use variables for customization. Avoid hardcoding organization IDs, device serials, IP addresses, or credentials in workflow logic. Use input variables marked as required so that workflows fail clearly if critical input is missing.
-
Implement consistent error handling. Enable “Continue Workflow execution on failure” where appropriate and add condition blocks to check the previous activity’s Succeeded property. Every workflow should set standard output variables: Result, Status Code, Status Message, and Error Message.
-
Use Secure Strings for sensitive data. API keys, passwords, and other credentials should always be stored as Secure Strings, never as plain-text variables or default values.
-
Decompose into sub-workflows and atomics. Complex automations should be broken into smaller, reusable components. This reduces variable sprawl, simplifies debugging, and enables the composition of larger automations from tested building blocks.
-
Treat workflows like code. Version-control workflows by exporting to Git repositories. Use the Validate function before execution. Test in staging before deploying to production organizations.
-
Be aware of Cisco Workflows limits. Workflows are not intended to be large, comprehensive scripts, used for infinite/long running loops, or the primary source of config management, but rather targeted, repeatable tasks that don't have native Dashboard functionality or customization.
Multi-Organization Considerations
Cisco Workflows can operate across multiple Meraki organizations in a single workflow run when the workflow uses runtime Targets and appropriately scoped credentials.
For enterprise deployments, avoid copying the same workflow into every organization. Instead, use a Target that accepts the organization ID at runtime, or a Target with an API key authorized to operate across the required organizations. This keeps the workflow definition centralized while making the execution scope explicit and auditable. Use organization-local targets or imports only when isolation is required or the workflow cannot safely span organizations.
For workflows that must remain organization-specific, use Git-based export and import to maintain version consistency. The Exchange synchronizes across regions, but custom workflows that are not published to the Exchange must still be managed through Git-based import and export.
Relationship to the Dashboard API
Cisco Workflows complements, rather than replaces, direct API scripting. The Dashboard API remains the right tool for high-frequency polling or data-intensive reporting, and integrations embedded within existing CI/CD pipelines or IaC toolchains such as Terraform and Ansible.
It excels for multi-step operational processes that benefit from visual design, approval gates, scheduled execution, and built-in error handling — particularly for teams without dedicated software engineering resources. Together, the Dashboard API and Workflows provide complementary automation capabilities: the API for developer-centric integrations and Workflows for operations-centric automation.
Cisco Workflows are currently subject to the same PAI rate limitations as Meraki API calls. 10 calls per second per organization, with the ability to burst up to 30 calls per two seconds. The Workflows adapter that makes calls to the Meraki API includes a backoff and retry mechanism that will automatically back off and retry up to 5 times before reporting a Meraki API failure to the Workflow.
Cisco Meraki MCP Server
The Cisco Meraki MCP Server connects AI agents and coding assistants like Claude, Cursor, and VS Code directly to the Meraki Dashboard API through the Model Context Protocol (MCP) standard. It enables natural language queries and agentic network automation without writing custom API integration code. Use it to build agents that generate reports, troubleshoot connectivity issues, audit configurations, and answer questions about your network using conversational prompts.
This MCP server follows the Dashboard API rate limits. Please follow the developer documentation to get started.
The Meraki MCP is currently in Beta for all customers to try and provide feedback for improvement as we make it generally available in the near future.
AI-Assisted and Cross-Domain Operations
Cisco Meraki provides cloud-native tools that help network teams operate large, distributed environments with less manual effort. Cisco AI Assistant for Networking adds natural-language assistance directly within the Meraki Dashboard, while Cisco Cloud Control extends operational context across supported Cisco domains. Together, these capabilities complement the Dashboard API and Cisco Workflows by helping administrators move more efficiently from observation and investigation to an approved operational action.
Cisco AI Assistant for Networking
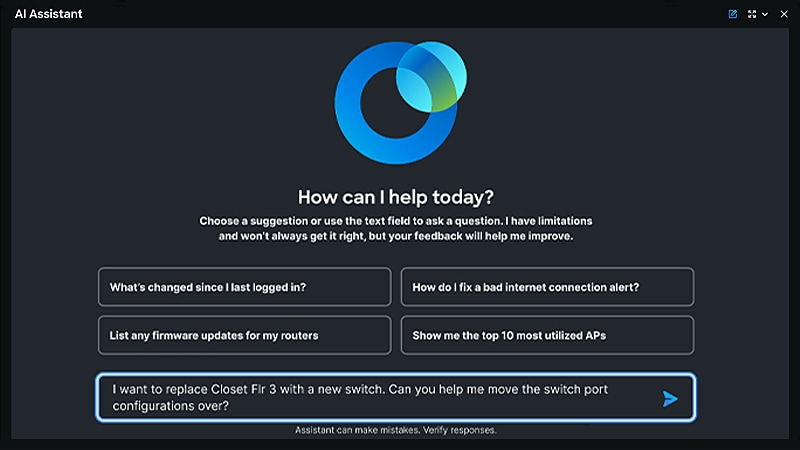
Cisco AI Assistant for Networking is a conversational capability integrated into the Cisco Meraki Dashboard. It allows administrators to ask questions in natural language and receive context-aware information derived from supported Dashboard data, Cisco networking knowledge, and published Meraki documentation. This reduces the need to navigate among multiple Dashboard pages or manually correlate information during routine monitoring and troubleshooting.
The assistant is intended to accelerate common Day 0 through Day 2 activities. Depending on the capabilities available in a given cloud and organization, administrators can use it to summarize network health, investigate client and device behavior, obtain configuration guidance, interpret screenshots or diagrams, review support-case summaries, and initiate supported automated workflows. Responses may adapt to the question by presenting explanatory text, structured results, or purpose-built user-interface elements.
Deep Reasoning Mode
Use Default Mode for a direct status, device, or product question. Select Deep Reasoning Mode when an investigation requires the assistant to examine and correlate multiple data points, devices, networks, or time periods. It can return findings, likely causes, supporting evidence, and prioritized next steps for the operator to assess.
For example, an operator investigating reports of slow service across multiple sites can ask the assistant to compare WAN, switching, and wireless conditions, identify likely bottlenecks, and prioritize follow-up checks. State the relevant time range and site or network; the assistant uses the organization and network currently open in the Dashboard unless another target is identified in the prompt.
Deep Reasoning Mode provides analysis and recommendations; it does not change network configuration. Users must verify findings against current Dashboard data and evaluate any proposed remediation before implementing it through the approved change process. Users with the required administrator rights may also be able to run supported Meraki Live Tools diagnostics, such as ping or traceroute.
Operational use cases
Troubleshooting: Summarize symptoms, identify relevant devices or clients, and provide guided diagnostic steps using Dashboard context and Cisco documentation.
Network visibility: Retrieve and summarize health, inventory, configuration, client, and activity information by using natural-language requests.
Operational guidance: Explain Meraki capabilities, configuration options, and recommended procedures without requiring the operator to locate each source article manually.
Workflow initiation: Assist operators in discovering or launching supported Cisco Workflows for repeatable tasks, subject to the permissions and controls associated with the workflow.
Collaborative support: Summarize support cases and accept visual inputs, such as screenshots and diagrams, when those capabilities are available.
Cisco Cloud Control
Cisco Cloud Control is a cloud-based operational platform designed to unify supported Cisco products and domains within a common experience. It provides a shared operational layer for networking, security, compute, observability, and collaboration platforms, with capabilities such as unified access, inventory, topology, prioritized actions, AI-assisted investigation, and extensibility to supported third-party systems.
For a Meraki deployment, Cisco Cloud Control complements rather than replaces the Meraki Dashboard. The Meraki Dashboard remains the authoritative management platform for Meraki organizations, networks, devices, configuration, licensing, and product-specific monitoring. Cisco Cloud Control consumes permitted product context and provides a broader cross-domain view, allowing operators to investigate dependencies and conditions that may span Meraki and other supported platforms.
AI Assistant and AI Canvas
Cisco Cloud Control includes an AI Assistant as a natural-language entry point for questions, context gathering, and investigations. An operator can begin with a conversational query and, when an issue requires deeper analysis or collaboration, create an AI Canvas while preserving the conversation context. AI Canvas provides a persistent workspace in which people and supported AI agents can organize evidence, investigate an issue, and coordinate actions across domains.
This operating model is particularly relevant to large enterprises in which user experience and service health depend on multiple infrastructure domains. For example, an investigation may begin with a client or site condition visible in the Meraki Dashboard and then require topology, assurance, security, or application context from another supported Cisco platform. Cloud Control is intended to reduce context switching while retaining links to the source systems that own the underlying data and controls.
Relationship to existing Meraki operational tools
The Meraki Dashboard, Dashboard API, Cisco Workflows, AI Assistant for Networking, and Cisco Cloud Control serve complementary operational roles. The Dashboard provides the native graphical management experience; the API supports developer-driven integrations and infrastructure-as-code practices; Workflows provides governed low-code automation; AI Assistant provides conversational access to information and supported actions; and Cloud Control provides cross-domain context and collaborative agentic operations. Large-scale designs should select the appropriate tool for each operational process instead of treating any one interface as a universal replacement for the others.
Monitoring, reporting, and troubleshooting
Use the Dashboard for operational context, webhooks for event-driven alerting, syslog for retained event history, SNMP where an existing NMS requires it, and the API for fleet-scale status and reporting. Select a primary signal for each incident class so operators do not receive duplicate alerts without a defined response.
|
Source |
Strength |
Design guidance |
|
Dashboard |
Context-rich health, client, WAN, wireless, switch, and security views. |
Use for investigation and interactive operations. |
|
Webhooks |
Near-real-time JSON event delivery to an HTTPS endpoint. |
Use for alert routing and automation. Start with high-value events and protect against duplicate or burst delivery. |
|
SNMP |
Compatibility with established NMS polling and metrics. |
Use SNMPv3 where supported; size polling and timeouts for the fleet. |
|
Syslog |
Longer-lived event records from MX, MR, and MS devices. |
Use when dashboard history is not sufficient for audit, incident, or trend analysis. |
|
Dashboard API |
Filtered, paginated, programmatic access to inventory, state, metrics, and events. |
Use for fleet reporting, compliance scans, and integrations that need structured data. |
Webhook controls
- Use an HTTPS endpoint with a certificate trusted by the public certificate chain. Confirm that the receiver permits traffic from the Meraki Cloud source ranges required by the service.
- Validate the webhook payload, authenticate the sender where supported, make processing idempotent, and retain the event identifier or timestamp needed to deduplicate retries.
- Begin with device offline, WAN failover, security, and other events that have a defined owner and response. Expand only after alert volume and operational value are measured.
SNMP and syslog boundaries
Meraki supports cloud-based and local-device SNMP polling with different visibility and network-path characteristics. Confirm whether the NMS should poll the cloud or the device, and test NAT, ACLs, UDP reachability, credentials, and polling intervals. SNMP traps are cloud-originated; a receiver behind NAT may require an explicit forwarding design.
Syslog is configured per network under Network-wide > Configure > General. MX can report event log, IDS alerts, URLs, and flows; MR can report event log, URLs, and flows; MS currently reports event log messages. Retain logs in a system with an access, retention, and time-synchronization policy.
Troubleshooting sequence
- Confirm the scope: organization, network, device, client, uplink, VLAN, or policy.
- Check current device reachability and cloud status before changing configuration.
- Compare the effective device state with the intended template, tag, firmware, and local override state.
- Use the event log, packet capture where authorized, client timeline, and uplink statistics to isolate the first observable failure.
- Test the smallest reversible change in a pilot or maintenance window, then record the result in the change record.
Operational efficiency
Change management
Use the organization change log as the Dashboard audit trail, but connect it to the broader change-management process rather than treating it as approval evidence. Track and notify on configuration changes through the appropriate combination of Dashboard API queries, webhooks or push notifications, and email alerts. Use the API for scheduled reconciliation and reporting, push notifications for near-real-time operational response, and email for human escalation. Confirm event coverage, delivery behavior, and ownership for each notification method.
For high-blast-radius changes, record the request, owner, source of truth, test evidence, affected scope, maintenance window, success criteria, and recovery procedure before execution.
A useful staged rollout is a small pilot group, an observation period that matches the failure mode, and controlled expansion. Select the pilot size and observation interval based on the risk and traffic pattern of the change rather than applying a universal rule.
Configuration drift
- Scan for local overrides, inconsistent tags, unsupported firmware, missing VLANs, and deviations from the template contract.
- Use infrastructure as code, such as Terraform or another approved declarative tool, when configuration requires repeatable desired-state management. Define which resources the tool owns and reconcile changes through reviewed plans rather than allowing competing sources of truth.
- Treat a manual change as either an approved exception with an owner and expiry date or a defect to be reconciled.
- Keep a configuration backup or exported representation of critical intent, including addressing, VLANs, routing, firewall policy, SSIDs, and administrator scope.
- Use API polling, webhook events, and scheduled comparisons to identify drift; do not assume that a single notification method captures every configuration change.
- Review drift by site archetype and owner so the result becomes an actionable queue rather than a fleet-wide exception report.
Capacity and continuity
Track organization and network device counts, API consumption, network size, VPN topology, log volume, and wireless roaming-domain size. Maintain offline documentation for critical site recovery, including the management VLAN, WAN handoff, addressing, trunk requirements, upstream dependencies, and support contacts.
During a cloud-management outage, devices can continue forwarding with their cached configuration, but operators cannot assume that telemetry, configuration changes, firmware, or inventory operations will be available. Define which local services must continue, how an emergency change is authorized, and how the state is reconciled after access returns.
Design pitfalls and review checklist
Use this checklist during design review and before production handoff. Each answer should link to a diagram, configuration record, test result, or named owner.
- Organization scale, region, licensing, SD-WAN domain, and growth assumptions are documented.
- Every network has a physical or operational boundary, a site archetype, an owner, and a naming standard.
- Template ownership, local overrides, cloning behavior, tags, and API responsibilities are explicit.
- Cloud firewall requirements were taken from the current Dashboard Help > Firewall info page for the applicable service.
- Mixed Meraki/Catalyst STP behavior was tested, including VLAN 1, trunk mode, root placement, and blocked-port behavior.
- Wireless roaming domains match RF adjacency and wired VLAN boundaries; inter-AP communication is permitted where required.
- SSID count, channel width, minimum bitrate, transmit power, 6 GHz policy, and mesh behavior match the RF design.
- Auto VPN hubs, spokes, advertised routes, uplinks, failover behavior, and overlay scale have been modeled and tested.
- Firmware release channel, pilot group, maintenance window, upgrade order, and recovery criteria are recorded.
- Monitoring ownership is assigned for Dashboard, webhooks, SNMP, syslog, API reports, and security events.
- API service accounts, permissions, secrets storage, rate-limit handling, pagination, retries, and audit logging are implemented.
- Offline recovery documentation and post-outage reconciliation steps are available to the operations team.
Additional resources
The following Cisco and Cisco Meraki pages are the authoritative references for the recommendations in this guide. Verify current page titles, product support, menu paths, regional endpoints, and limits before implementation.
Building a Scalable Meraki Solution
Configuring Spanning Tree on Meraki Switches
Meraki Wireless for Enterprise Best Practices Architecture
Meraki Wireless for Enterprise Best Practices RF Design
Auto VPN Hub Deployment Recommendations
Meraki Auto VPN General Best Practices
Auto VPN Static Routing Principles and Scaling Techniques
Meraki Dashboard Login Authentication Options
How to Use the Cisco Meraki Dashboard API
Cisco Meraki Device Reporting Syslog SNMP and API